

“We already have a coding agent. Why would we need Coalesce?”
That question has come up a lot lately in conversations with data engineers. The name of the agent shifts—Claude Code, Codex, Cursor, or recently, Cortex Code—but the reasoning behind the question stays the same.
It’s a fair question, but the way it’s usually framed hides a false comparison, and that’s worth clearing up first. There isn’t a “Coalesce AI” sitting across the table from your AI. When a customer points Cursor or Claude Code at the Coalesce MCPs, it’s still Cursor or Claude Code. Same model, same agent, same terminal. Swap in Codex or Cortex Code and nothing about the answer changes.
The real comparison is your agent working alone versus the same agent working through a platform that knows how to build data pipelines for enterprise data environments at scale. That distinction is the whole answer, and this post aims to unpack it.
What coding agents do well: the fast 80% of pipeline code
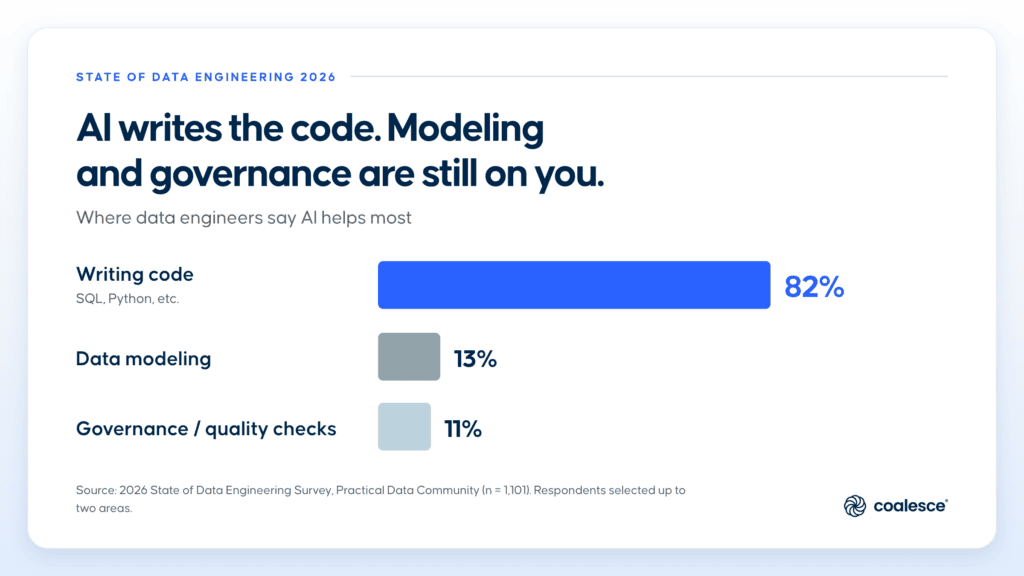
The model deserves its due. Point Codex, Cursor, Cortex Code, Claude Code, or any coding agent at a set of source tables and request a dimension. Type 2 SQL appears within minutes. As Doug Barrett, our field CTO, described in a recent webinar: tasks that once took a week now finish in twenty minutes. Agents routinely generate staging layers, fact tables, and migration scripts at a pace that outstrips manual typing. The 2026 State of Data Engineering Survey offers some perspective: 82% of data engineers say AI assists them with coding. Just 13% find it helpful for data modeling, and only 11% see benefits for governance.
Most engineers who work with these agents day to day describe the same pattern: a coding agent gets you about 80% of the way there on any given piece of pipeline code, and it gets you there fast. The last 20% is judgment. Is this the right grain for the fact table? Does this join actually do what the business thinks it does? Does “revenue” here mean what finance means by revenue? Those questions were never about typing speed, and no model answers them for you. The Coalesce agentic data engineering platform was designed on exactly this assumption: the agent generates most of the code, and the humans move to planning, design, and review, where their time is worth more.
Where AI coding agents break: 20 tables, 200 tables, 2,000 tables
So if the agent is good at the 80%, what’s the problem? Scale. Michael Tantrum, who runs sales engineering at Coalesce, has a line that gets repeated on a lot of calls: “Twenty objects, piece of cake. Two hundred, I’m starting to sweat. Two thousand, I’m throwing my hands up.” The first 20 tables an agent builds look great. You can read them, reason about them, and understand what it did. The trouble starts when you go back for more, and it shows up in three places.
Code with no structure
LLMs are non-deterministic. Ask for a dimension on Monday, and you get one implementation of slowly changing logic. Ask on Tuesday, and you get a different one. Multiply by two engineers with their own agents and prompts, and you have four patterns for the same thing. When one of them goes on vacation, you’re reading somebody else’s agent’s idea of a dimension. Add the classics on top: a customer_name column that doesn’t exist because the source has first_name and last_name, or a join the agent assumes that turns out to be Cartesian and shows up on the Snowflake bill first.
Data with no context
The agent doesn’t know what “revenue” means at your company. It doesn’t know where the data came from, who owns it, or that a nearly identical data set already exists two schemas over. So it builds another one. Doug was blunt about this on the webinar: “When it’s hard to understand what’s already there, it’s easier to start again, and now you have duplication on top of everything else.” Humans can usually piece things together when context is missing. An agent can’t.
Trust with no proof
Michael’s other nugget of wisdom: “Trust is earned in pennies and spent in dollars.” One bad figure sends the business back to spreadsheets. When an agent writes the pipeline and nobody reads it all, the CFO asking where a number came from is a scarier question than it used to be. You need lineage back to source in the meeting, not in two weeks. None of that is the model’s fault. The model did what it was asked. The problem is what it was working against: nothing. No standards to follow, no context to read, and no place for a human to check its work that wasn’t a diff of generated SQL. Here’s what changes when the same agent works through Coalesce.
Four things Coalesce adds to the AI coding agent you already have
Coalesce is the data operating layer where humans and AI agents build, govern, and observe data together. Here’s what that means mechanically, for the agent you’re already running.
1. Standards are enforced from the DDL up
In Coalesce, a pipeline is built from Nodes, and every Node has a Node Type: source, staging, dimension, fact, view, and so on. The Node Type is where the standards live, and they aren’t suggestions. When an agent (or a person) creates a dimension Node, the Node Type generates the DDL, and that DDL carries the naming convention, the surrogate key, the system columns for effective dates and current-record flags, and the storage location. You can’t get a non-conforming dimension out of a dimension Node. There’s no path to one.
In the recent webinar demo, Doug took a raw drivers table and turned it into a dimension. Without typing anything, the Node applied the naming standard, added the surrogate key, added the system columns, and landed itself in the gold layer. Then he ran it and showed the generated Type 2 SQL, which isn’t trivial. His point: “This code’s gonna look the same regardless of whether it’s this dimension or another dimension or the twenty other dimensions I’m gonna build.”
That’s the difference: one agent tries to recall your standards every time, while another simply inherits them. That keeps 2,000 objects manageable. Even the largest warehouses rely on just a few patterns, so you’re reviewing structures, not individual lines of code. Coalesce 2.0 builds on this by adding a policy layer—if your standard calls for Type 2, the agent can’t override it.
2. Patterns the agent picks up from Coalesce platform skills
Some standards don’t live inside a single Node. Don’t go straight from a source to a fact; put a staging Node in between. Use a view Node for this, a dimension Node for that. Run the CLI this way, not that way.
DDL can’t enforce those, so Coalesce ships them as Coalesce platform skills: a packaged set of instructions that teaches your agent how to work with the platform. The agent still does the building. It just builds the way your team would.
The demo showed this in action. Doug asked the agent to build dimensions and facts over a set of source Nodes, and it inserted staging Nodes on its own, because the skill told it a source shouldn’t feed a target directly. It used staging, dimension, fact, and view Node Types and nothing else. Enforcement at the Node level plus guidance at the pattern level is what makes the output consistent across agents, engineers, and weeks.
Platform skills are part of the Coalesce local development experience.
3. The last 20%: human judgment at work
The agent handles the code. But agreeing on modeling standards, designing the architecture, deciding what governance applies, and knowing whether the numbers are actually right are still hard problems to solve.
The question is where that judgment happens. Sifting through endless SQL diffs isn’t scalable. Coalesce puts the answer in front of you: a pipeline graph, Node inspection, and column-level lineage in the platform, plus Coalesce Desktop (now generally available) for local work—where Nodes appear as the agent creates them, before anything is deployed.
Coalesce gives you a review surface for AI-built pipelines. Instead of reading code line by line, you see whether the right Nodes are used in the right way, and whether the pipeline structure matches your standards.
“Human-in-the-loop” is a common claim, but few vendors can show you where the human fits. Here, it’s visual: every attribute’s path through the pipeline, every transformation defined at the column level.
The agent follows the same process as your senior engineers. Access is governed by tokens—read-only by default, write granted on purpose. All work, agent or human, goes through the same review and deployment steps. The audit trail shows exactly which changes came from an agent and which from a person. If you’d protect a production database credential, treat an MCP write token the same way.
4. Transform, Catalog, and Quality: one context layer
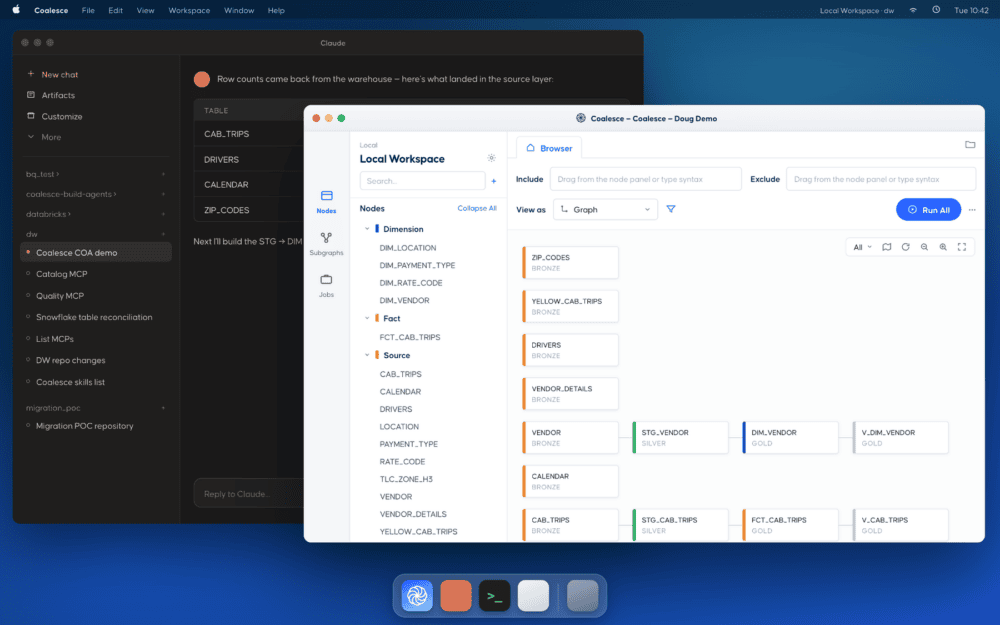
Transform, Catalog, and Quality all draw from a single metadata source. That’s not just organizational—it’s what lets agents operate with real context.
Think about what every engineer needs before changing a field: What will break downstream? Is the source healthy? An agent working alone can’t answer that. With only one product’s MCP, it’s a partial view. In Coalesce, you have it all—lineage in Catalog, code in Transform, monitor status in Quality—because everything shares a metadata layer underneath.
Catalog gives the agent context up front: business definitions, ownership, tiers, documentation, and detailed lineage. If a subject-matter expert defines cost of goods sold (COGS) in Catalog, the agent reads that definition directly, no guessing. The 2.0 release expands this to metric definitions and PII masking rules. Instead of inferring meaning from column names, the agent on Coalesce has the definitions, SQL, and governance it needs. Quality provides signals the agent can act on. Tests and anomaly monitors run against every pipeline: range checks for the problems you expect, time-series anomaly detection for those you don’t. Ask the Quality MCP to surface issues on a fact table and then for the root cause, and it tracks the lineage and recent changes, finding—for example—test code that made its way to production.
Quality spots the issue, Catalog’s lineage locates it, and Transform fixes it. This loop works because all three share metadata. Scout, the always-on data SRE agent in Coalesce Quality, handles this triage in the background and proposes fixes, so the team reviews conclusions instead of chasing alerts. Scout recommends; a human approves.
Coalesce Quality is built on SYNQ, acquired in March 2026. The observability piece isn’t new—it’s an established enterprise solution trusted by leading data teams, now tightly integrated into Coalesce. What changes when the same coding agent works through Coalesce.
| Your coding agent alone | Your coding agent + Coalesce | |
|---|---|---|
| Standards | Has to remember naming, keys, and system columns every time; a different Type 2 each run | Inherits them from the Node Type; the DDL carries them every time |
| Patterns | Source straight to fact if that’s what the prompt implied | Platform skills put a staging Node in between and pick the right Node Type |
| The last 20% | A human reads generated SQL in a diff | A human reviews the graph and column-level lineage in Coalesce Desktop or the platform |
| Context and workflows | Knows what’s in the prompt; can’t ask what breaks downstream or whether the source is healthy | Reads definitions, ownership, and lineage from Catalog and status from Quality; impact analysis and root cause in one prompt |
| Governance | Whatever credentials it was handed | Same standards, approvals, and audit trail as an engineer; read-only by default |
| When it’s wrong | Hallucinated columns and Cartesian joins found in production | Caught at compile, at review, or by a monitor first |
Speed isn’t the problem anymore. Coordination is.
Your agent isn’t the problem, and Coalesce isn’t a different agent. A general-purpose coding agent will write your SQL faster than you can review it. What it can’t do on its own is inherit your standards from the DDL up, know which patterns your team builds with, give a domain expert somewhere to do the judgment work that’s still theirs, or run a workflow that crosses your definitions, your pipelines, and your quality signal in one pass.
Coalesce gives the agent you already have all four, under the same governance your engineers already work in.
To see what your agent can really do, begin with prompts: run impact analysis before changing a field, or identify root causes when a monitor fires. If a prompt becomes routine, turn it into a team-built skill. If it needs to run on a schedule with controls, make it a playbook.